The five primitives behind always-on agents
Always-on agents are mostly asleep: an event wakes a worker, a short run executes, state is written back, and the agent sleeps again. The post decomposes the surrounding architecture into five primitives. An event inbox (durable table + handler + worker) replaces letting each event source call the agent directly, avoiding competing runs and lost events on crash. Timers split into agent-set follow-ups and recurring schedules, stored separately and fired by a polling scheduler that writes into the inbox. Memory is a directory of files for user instructions, user notes, past messages and task progress, with the rule that memory only holds what cannot be looked up elsewhere. Permissions rely on a credential-injecting proxy, classifier-based auto mode, and deferred tool calls that end a run mid-call and resume it from a new event. An outbox with a dispatcher paces delivery and enables retries. The only hard number is a 78% per-task cost drop on a long-horizon coding benchmark versus 40% on typical workloads.
Over the past few months, we’ve seen a resurgence of always-on agents.
Always-on agents are stateful and proactive, meaning they manage context across sessions and take actions without direct supervision. Underneath, they run on the same core loop as other agents. The difference is the surrounding architecture, which is built from primitives that control when the agents wake up, what carries over between runs, and how their work reaches the user.
过去几个月,常驻/always-on 代理(agent)重新活跃起来。
常驻代理有状态、会主动行动:它们跨会话管理上下文,无需人直接监督就能采取动作。底层和其他代理一样,跑的是同一套核心循环。区别在于外围架构:这套架构由若干原语组成,分别控制代理何时醒来、每次运行之间保留什么,以及工作成果如何送达用户。
The resurgence is largely due to recent model advancements, which have made always-on agents more practical to run. First, the latest models have better judgment: they’re more reliable at understanding user intent and knowing when to check in. Second, intelligence is becoming cheaper, with long-horizon tasks benefiting the most. For example, on one long-horizon coding benchmark, Opus 5.5 cost 78% less per solved task than Opus 5, compared with 40% less on typical workloads.
这波回归很大程度上得益于近期的模型进步,让常驻代理更具备可运行性。第一,最新模型的判断力更好:它们更能可靠理解用户意图,也知道什么时候该来确认。第二,智能正在变便宜,长周期任务受益最大。比如,在一个长周期编程基准上,Opus 5.5 每解决一个任务比 Opus 5 便宜 78%,而典型工作负载的降幅是 40%。
Customers have started to ask us how to integrate this type of experience into their own products. Some companies want to make their existing agents more proactive, while others are looking to build them from the ground up.
This post breaks down the primitives behind always-on agents and walks through how they fit together.
客户已经开始问我们,如何把这种体验接入自己的产品。有些公司想让现有代理更主动,有些则想从零开始构建。
这篇文章拆解常驻代理背后的原语,并说明它们如何组合在一起。
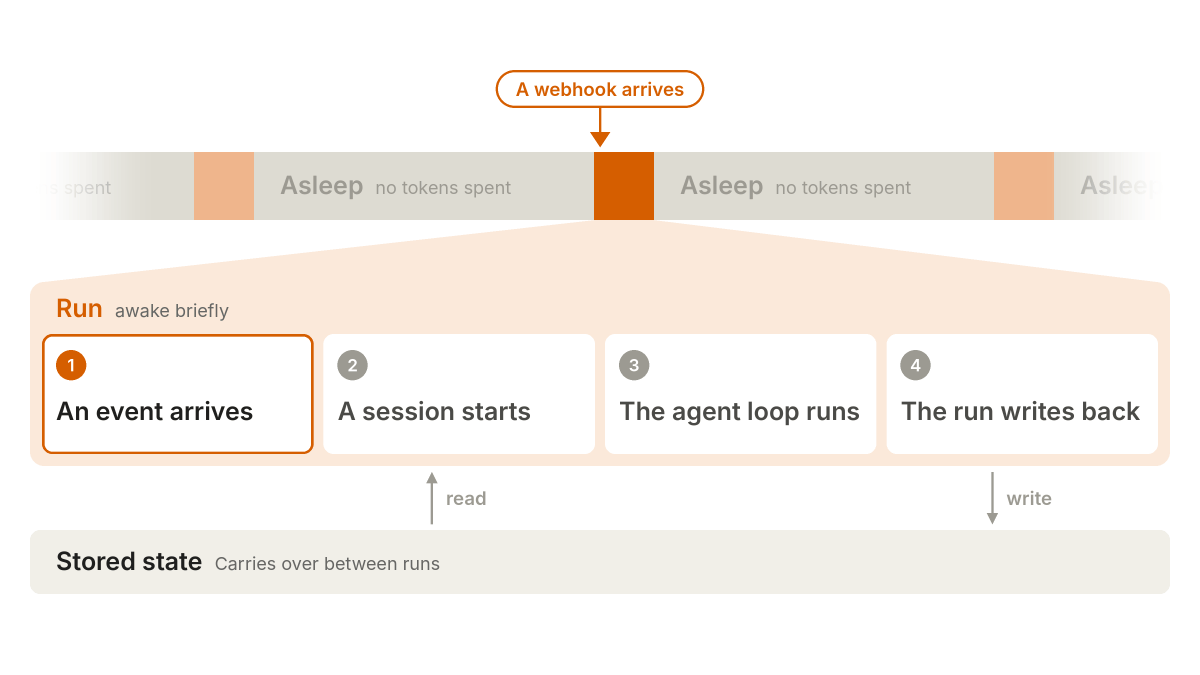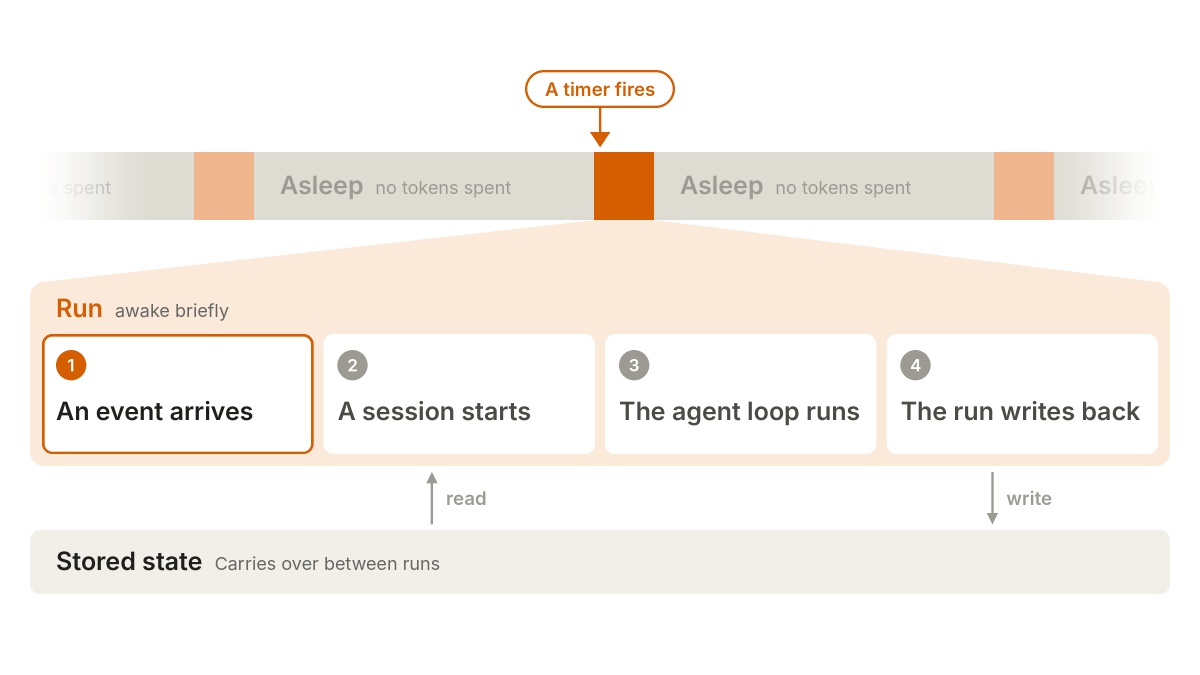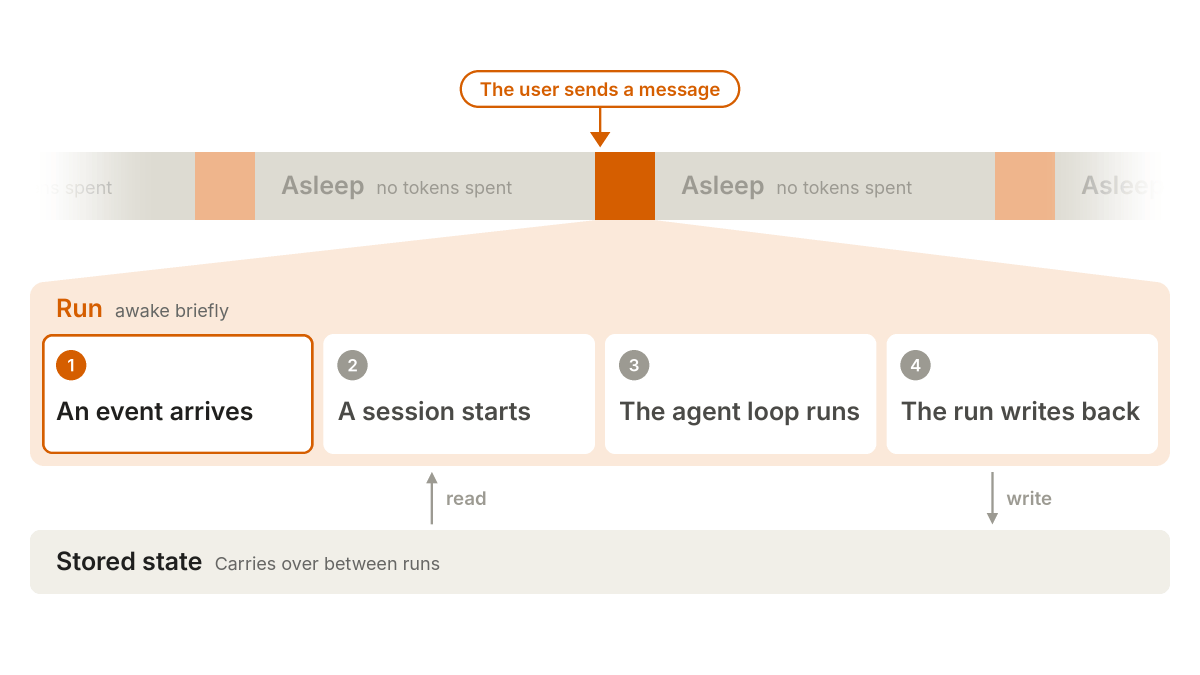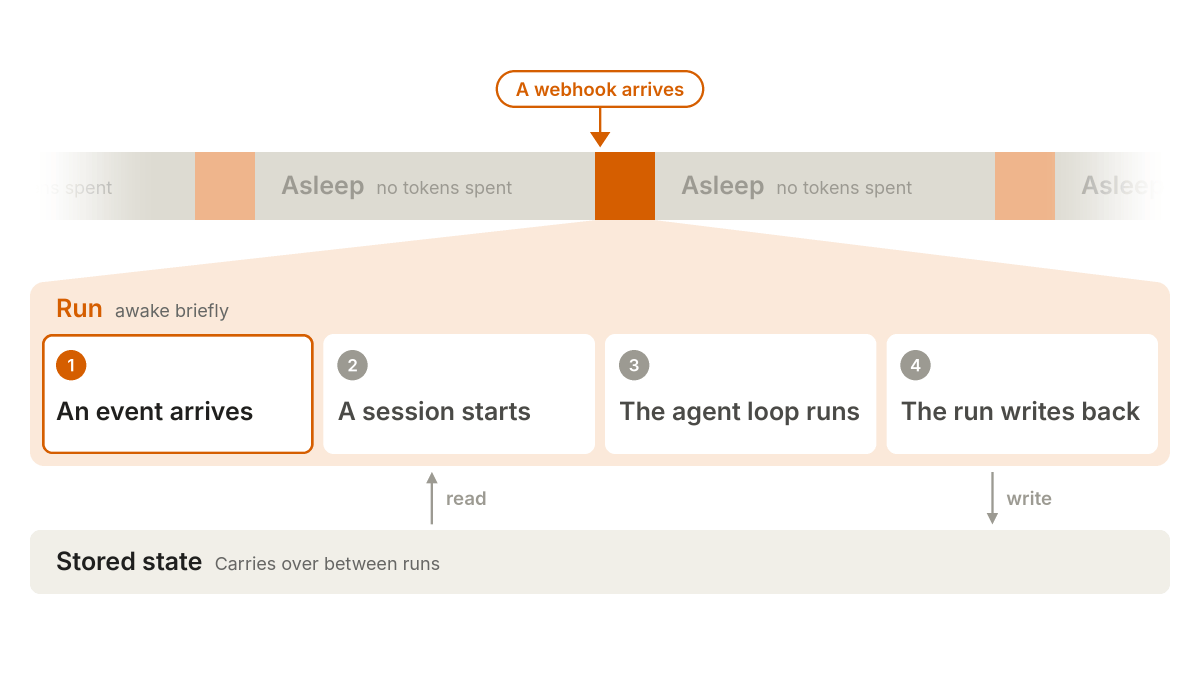
An always-on agent is not actually “always on.” This is just a description of the user experience.
In reality, the agent spends most of its time asleep, waking up periodically to do work. Each stretch of work is called a run: the agent receives an event, completes its task, and then saves information about what happened. A run works inside a session, which is the transcript of messages and tool calls. Once the run is finished, the agent goes back to sleep, and the cycle repeats indefinitely.
常驻代理并不是真的“一直在线”。这只是对用户体验的描述。
实际上,代理大部分时间都在睡眠,只是周期性醒来干活。每一段工作叫一次运行(run):代理收到事件,完成任务,然后保存发生了什么。一次运行发生在会话(session)里,会话是消息和工具调用的记录。运行结束后,代理重新睡下,这个循环无限重复。
The core primitives
The surrounding architecture of an always-on agent has five core primitives: an event inbox, timers, memory, permissions, and an outbox. Let’s take a look at each.
Event inbox
Most AI agents only run when the user sends a message. In contrast, always-on agents can be triggered by many types of events, including webhooks, scheduled tasks, and background jobs.
One tempting approach is to have each event source call the agent directly, but that has a few failure modes. For example, two events arriving at the same time can start competing runs, and a crash can lose an event entirely.
This is where the event inbox comes in. Instead of calling the agent, every source sends an event to an inbox, where a worker picks it up.
核心原语
常驻代理的外围架构有五个核心原语:事件收件箱、定时器、记忆、权限和发件箱(outbox)。下面逐一来看。
事件收件箱
大多数 AI 代理只在用户发消息时运行。常驻代理则可以被多种事件触发,包括 webhook、定时任务和后台作业。
一种很诱人的做法,是让每个事件源直接调用代理,但这会带来几种故障模式。比如,两个事件同时到达,可能启动互相竞争的运行;一次崩溃也可能让事件彻底丢失。
这正是事件收件箱要解决的问题。不要让事件源直接调用代理,而是把事件送进收件箱,由 worker 取走处理。
The simplest version has three components:
A durable list of events, usually a database table;
A handler, usually an HTTP endpoint, that writes events to the list; and
A worker, usually a background service, that reads from the list.
The inbox should track the status of each event, and events can be deduplicated based on unique identifiers from the source. A relational database works well for the inbox, with every event appended as a new row. We recommend starting with one inbox per user, but you can split this further if you need more parallelism.
最简单的版本包含三个组件:
一份持久化的事件列表,通常是数据库表;
一个 handler,通常是 HTTP 端点,负责把事件写入列表;以及
一个 worker,通常是后台服务,负责从列表里读取事件。
收件箱应该跟踪每个事件的状态,还可以根据事件源提供的唯一标识去重。关系型数据库很适合做收件箱,每个事件作为新行追加。我们建议先从每个用户一个收件箱开始,如果需要更高并行度,还可以继续拆分。
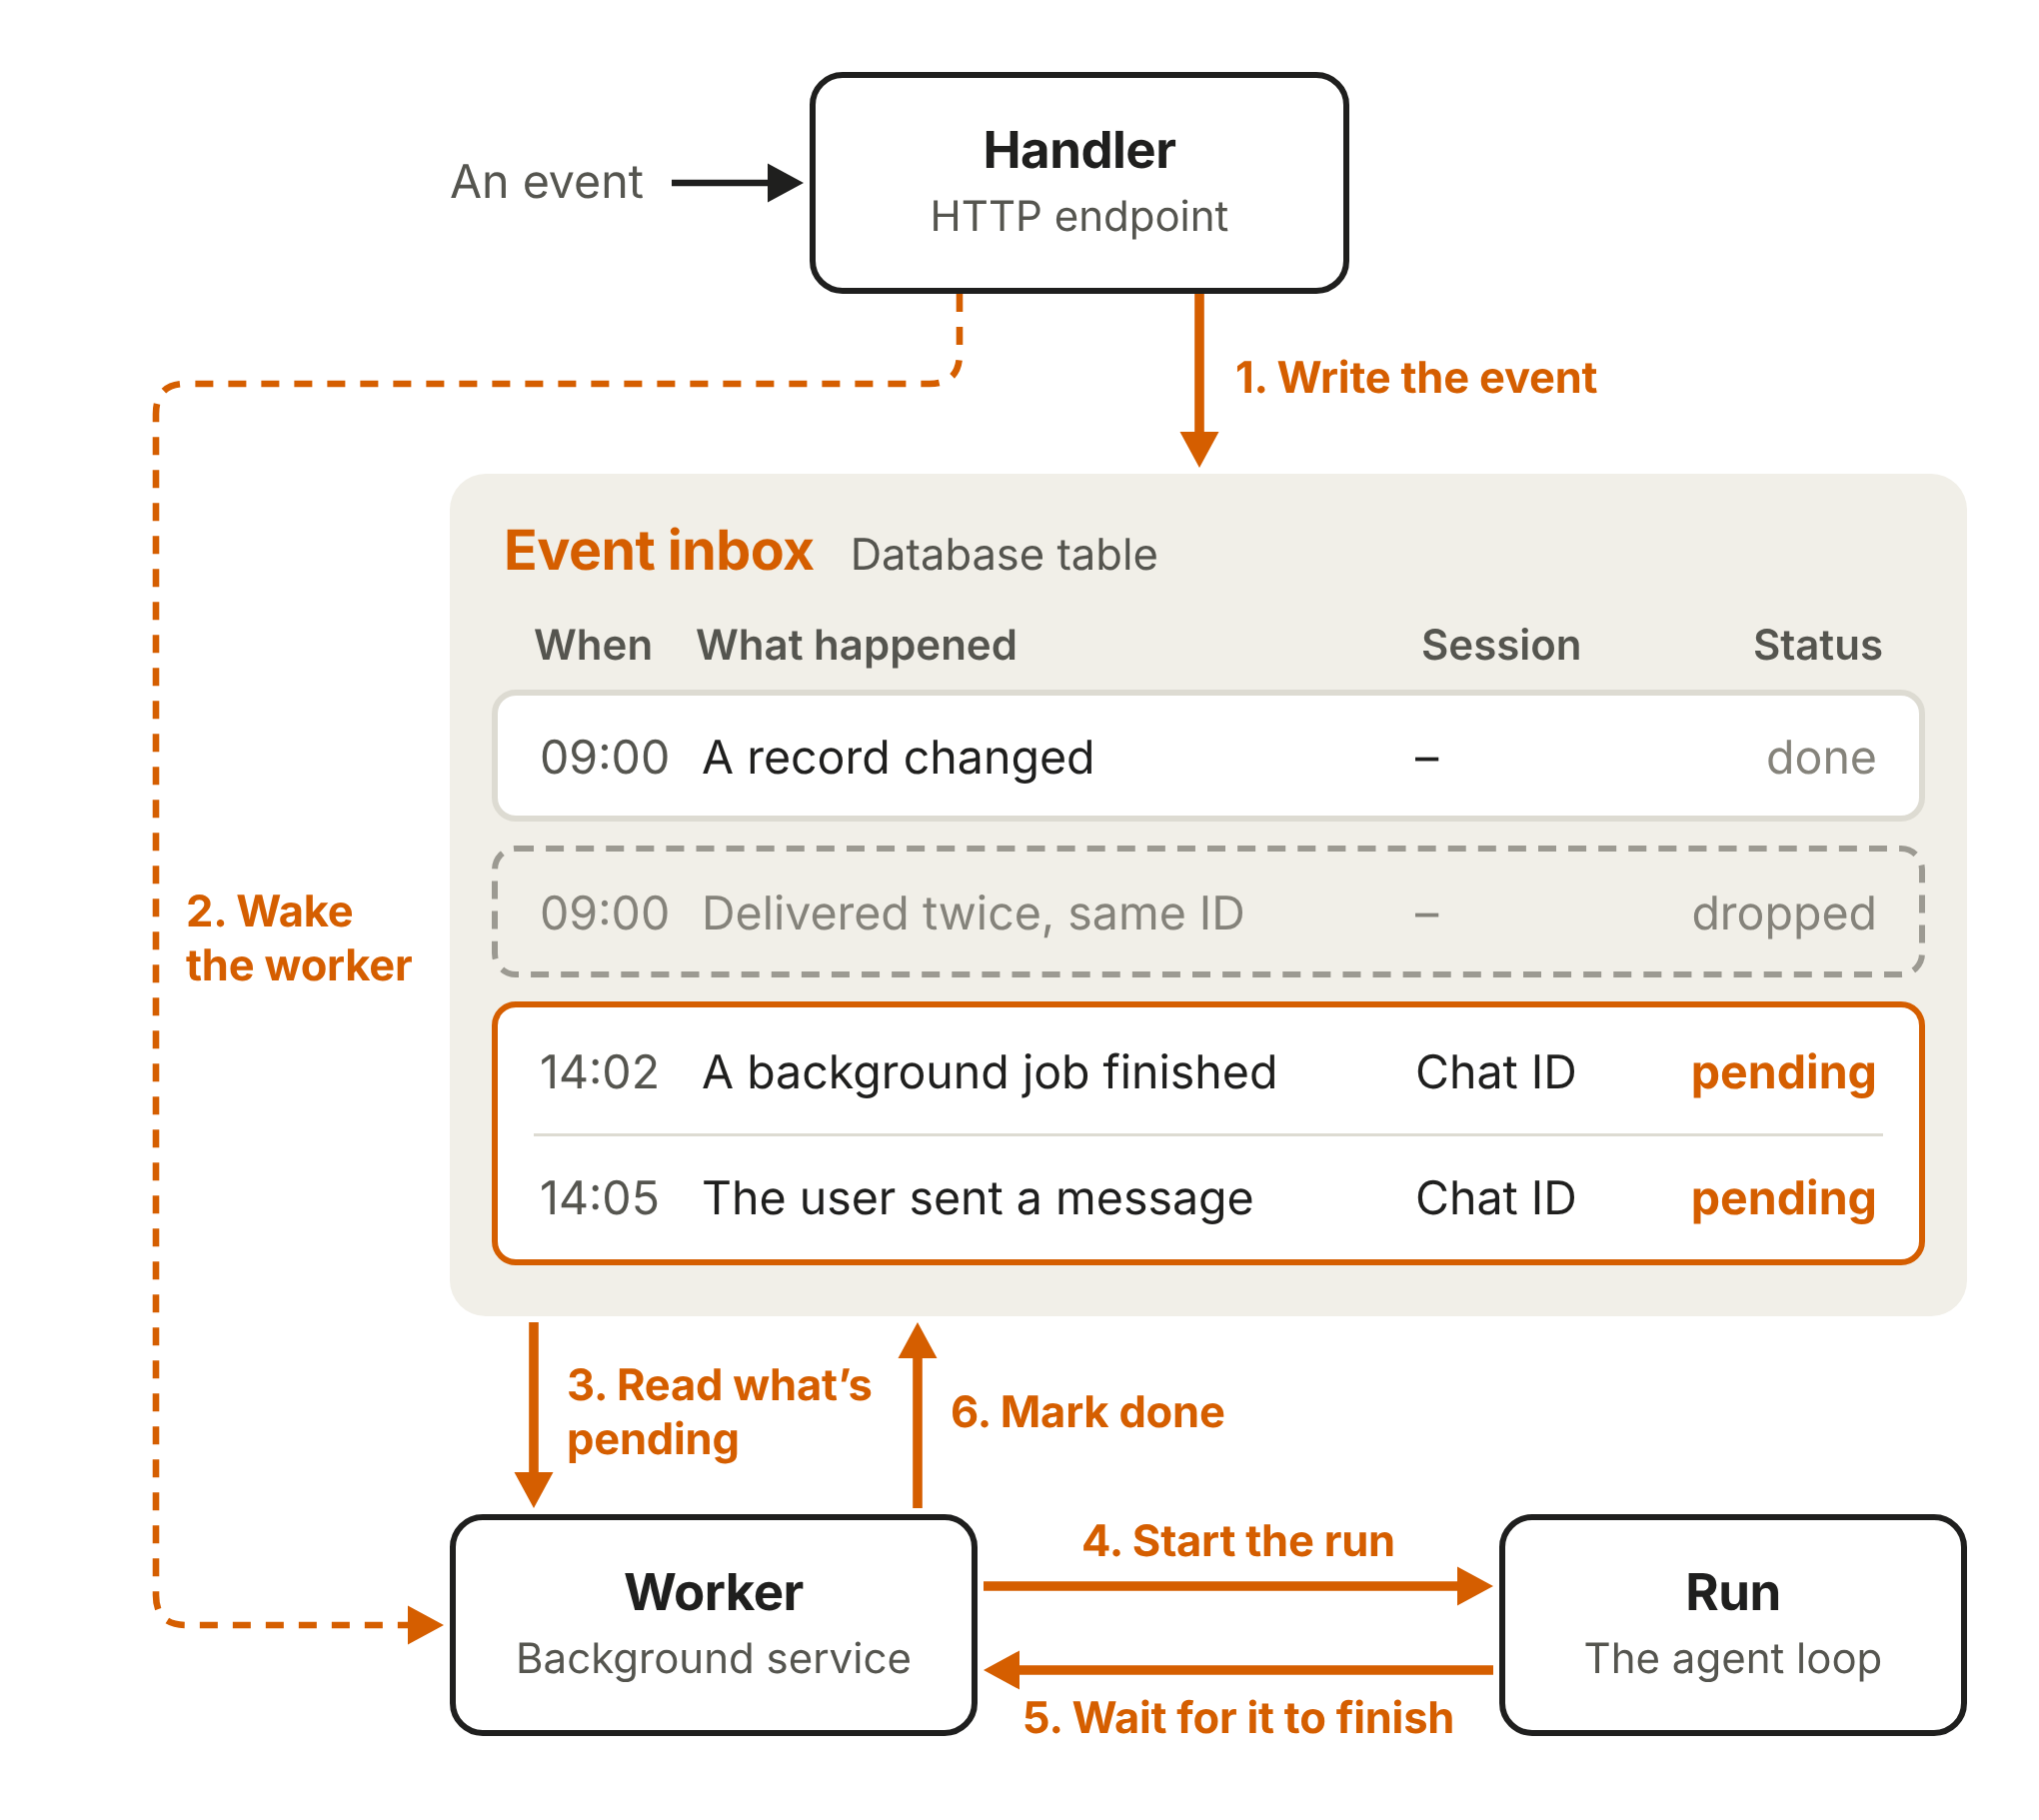
When a new event comes in, the handler writes the event to the inbox and wakes the worker. The worker reads whatever is pending and starts a run. Events that continue earlier work, such as a reply from the user, resume an existing session, while everything else starts a new session.
From there, the worker passes the events to the agent loop, waits for the run to finish, and marks the corresponding events as done. The implementation details can get tricky, so here are a few best practices:
The handler should acknowledge events quickly. Some sources, such as webhook providers, treat slow responses as failures. The handler can still run lightweight checks, but any deeper verification, such as checking for prompt injection, should be done during the run.
The inbox should be the source of truth. When the worker is woken up, it should pull the latest events from the inbox first. That way, if the worker dies mid-run, a new one can pick up the same event and retry.
An inbox should only have one active worker at a time. This prevents two runs from duplicating work or overwriting each other. When a new event shows up mid-run, you can either push it to the next run, fold it into the current run, or interrupt and restart.
The worker should batch pending events together. For example, if the user sends several messages in a row, the worker can merge them into a single run, so the agent only needs to reply once.
新事件进来时,handler 把事件写入收件箱,并唤醒 worker。worker 读取所有待处理事件,启动一次运行。如果事件是在延续之前的工作,比如用户回复,就恢复已有会话;其他事件则开启新会话。
接下来,worker 把事件交给代理循环,等待运行结束,再把对应事件标记为完成。实现细节可能很棘手,下面几条最佳实践值得注意:
handler 应该尽快确认事件。有些事件源(比如 webhook 提供方)会把慢响应当成失败。handler 仍然可以做轻量检查,但更深层的校验,比如检查提示注入,应该放到运行期间做。
收件箱应该是事实来源。worker 被唤醒时,应先从收件箱拉取最新事件。这样即使 worker 在运行中途挂掉,新的 worker 也能捡起同一个事件重试。
一个收件箱同一时间只应有一个活跃 worker。这能避免两次运行重复干活或互相覆盖。如果运行中途来了新事件,你可以把它推到下一次运行、并入当前运行,或者中断当前运行后重启。
worker 应该把待处理事件批量合并。比如用户连续发了好几条消息,worker 可以把它们合并成一次运行,让代理只回复一次。
Together with the event inbox, timers let always-on agents be proactive. Timers generally fall into one of two categories: follow-ups or schedules. A follow-up is a deadline that the agent sets for itself, such as checking in on a reply. A schedule, on the other hand, is a recurring task that happens on a known cadence, such as a daily newsletter.
Timers live in their own durable store, usually another database table, separate from the inbox. The inbox should only hold events that are ready to be worked on. A follow-up and a schedule can share a similar schema, but a schedule needs to track its recurrence as well.
定时器和事件收件箱配合,让常驻代理具备主动性。定时器通常分两类:跟进(follow-up)和日程(schedule)。跟进是代理给自己设的截止时间,比如到点查看某个回复。日程则是按已知节奏重复发生的任务,比如每日简报。
定时器放在自己的持久化存储里,通常是另一张数据库表,和收件箱分开。收件箱只应保存已经可以处理的事件。跟进和日程可以共用相似的 schema,但日程还需要跟踪重复规则。
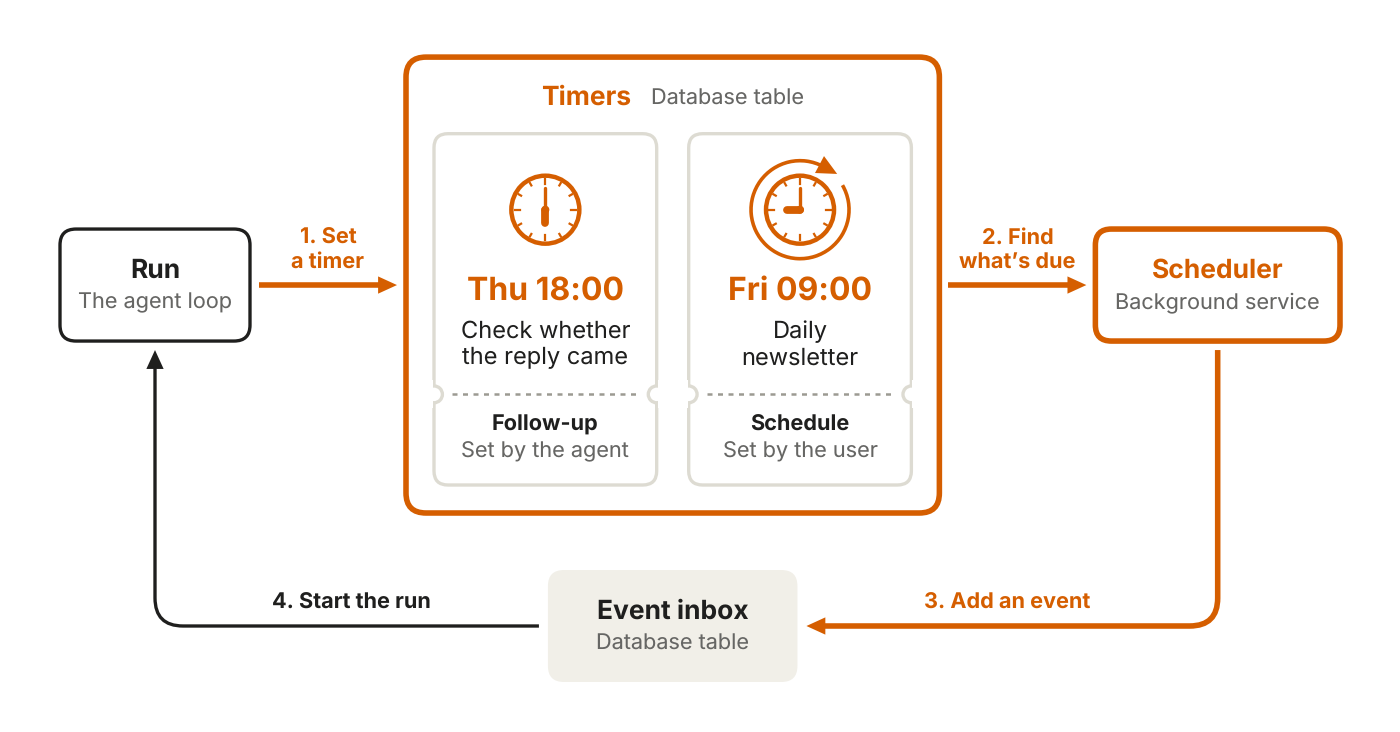
A timer doesn’t initiate a run on its own. Instead, a scheduler, usually a background service, polls the store at a fixed interval and fires anything that’s due. On each pass, the scheduler:
Scans the store and finds timers that are due.
Updates each timer based on its category. A follow-up should be marked as done.
A schedule should get its due time updated to the next occurrence.
Adds an event to the inbox and wakes the worker.
For the scheduler, you can either build your own service or use a durable execution engine.
定时器不会自己发起运行。真正干活的是调度器(scheduler),它通常是后台服务,按固定间隔轮询存储,并把所有到期项触发出去。每一轮,调度器会:
扫描存储,找出到期的定时器。
根据类别更新每个定时器。跟进应标记为完成。
日程应把到期时间更新到下一次发生的时间。
向收件箱添加事件,并唤醒 worker。
调度器可以自己写服务,也可以使用持久执行引擎。
Memory
Always-on agents work across many disjointed runs and rely on memory to maintain continuity.
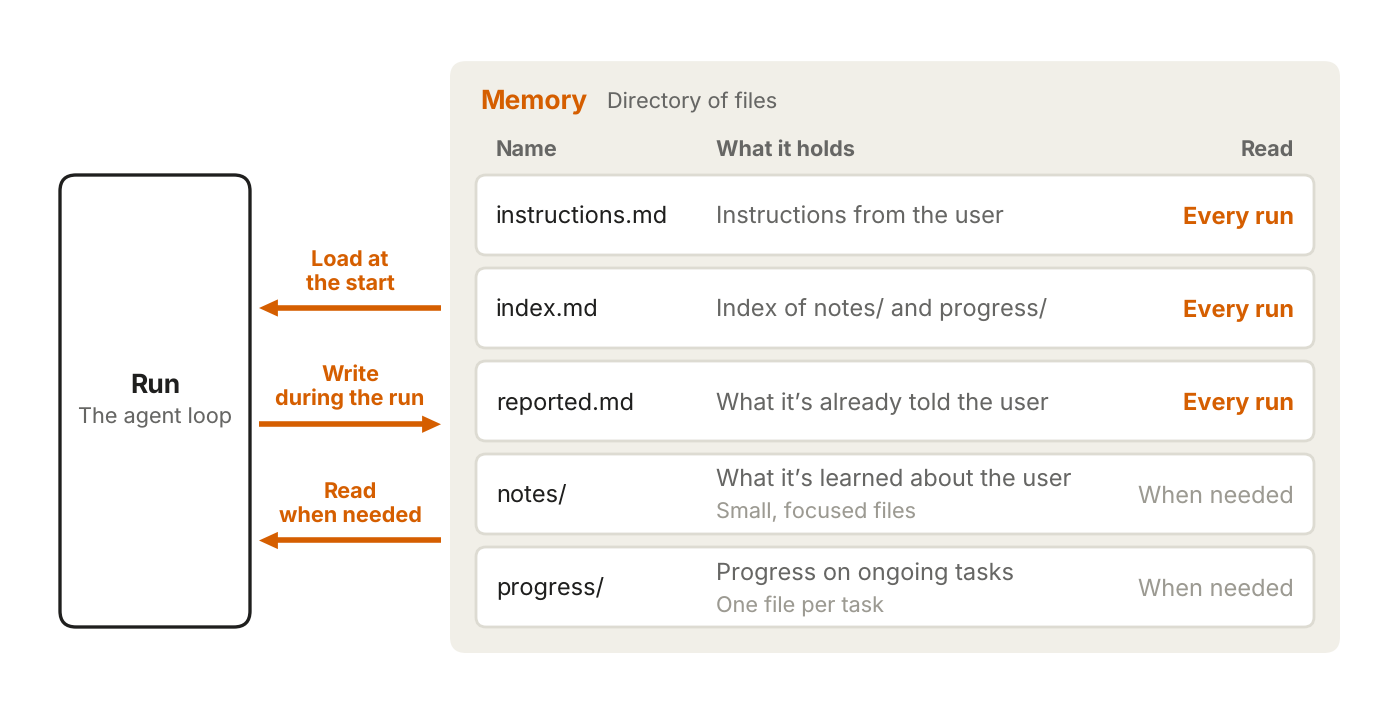
Similar to the event inbox and timers, memory should have its own store. In our products, such as Claude Code’s auto memory and the Messages API’s memory tool, this is implemented as a directory of files. For an always-on agent, the directories should map to durable storage, usually a database or an object store. This way memories outlive the worker.
As a rule of thumb, memory should only hold what the agent can’t look up again. If something already lives in another system, such as an issue tracker, you should save a pointer instead.
记忆
常驻代理要跨越许多彼此断开的运行,靠记忆保持连续性。
和事件收件箱、定时器一样,记忆也应该有自己的存储。在我们的产品里,比如 Claude Code 的自动记忆和 Messages API 的记忆工具,记忆实现为一个文件目录。对常驻代理来说,这些目录应映射到持久化存储,通常是数据库或对象存储。这样记忆的生命周期就能长过 worker。
一条经验法则是:记忆只保存代理无法再次查到的东西。如果某样东西已经存在于另一个系统,比如 issue tracker,就应该只存一个指针。
Here is a breakdown of the types of memory an always-on agent should store:
User instructions: Any instructions from the user about agent behavior should be saved in their own file and loaded at the start of every run. The user won’t always be around to steer the agent, so the instructions have to carry over between runs.
User notes: The agent should save what it’s learned about the user, such as their role, their preferences, or any corrections they’ve given. You can start with one file and move to several small files as the notes grow. In the latter case, only an index is loaded at the start of each run, but the agent can pull the individual files into context when it needs more details.
Past messages: The agent should keep track of what it’s already told the user so nothing is repeated. It can either store this in a separate file that’s loaded at the start of each run, or have the worker load the agent’s last few messages with the user.
Task progress: For each ongoing task, the agent should keep a progress file that covers what’s been done and what’s left. Any new run can then read that file and pick up where the previous run left off. Similar to user notes, only an index is loaded at the start of each run, but the agent can pull the individual files into context when it needs more details.
下面是常驻代理应该保存的几类记忆:
用户指令:用户对代理行为提出的任何要求,都应保存在单独文件里,并在每次运行开始时加载。用户不会一直在旁边给代理掌舵,所以指令必须跨运行保留。
用户笔记:代理应保存它了解到的用户信息,比如角色、偏好,或用户给过的纠正。可以先从一个文件开始,随着笔记增多再拆成多个小文件。后一种情况下,每次运行开始只加载索引,需要更多细节时,代理再把单个文件拉进上下文。
历史消息:代理应跟踪自己已经告诉过用户什么,避免重复。可以把这些存进单独文件,在每次运行开始时加载;也可以让 worker 加载代理与用户最近几条消息。
任务进度:对每个进行中的任务,代理应维护一个进度文件,记录已完成和剩余的工作。新的运行可以读取该文件,从上一轮停下的地方继续。和用户笔记类似,每次运行开始只加载索引,需要更多细节时再把单个文件拉进上下文。
All of the above describes memory that’s saved during a run. You can also add dreaming, which reviews past sessions to curate memories. Dreaming can replace outdated entries and find patterns that only show up across many runs. If you’re interested in learning more, our post on agent memory covers this in more detail.
以上说的都是运行期间保存的记忆。你还可以加入 dreaming,它会回顾过去的会话,用来整理记忆。Dreaming 可以替换过时条目,也能发现只有跨多次运行才会出现的模式。如果想了解更多,我们关于代理记忆的文章有更详细的讨论。
Inside the context window
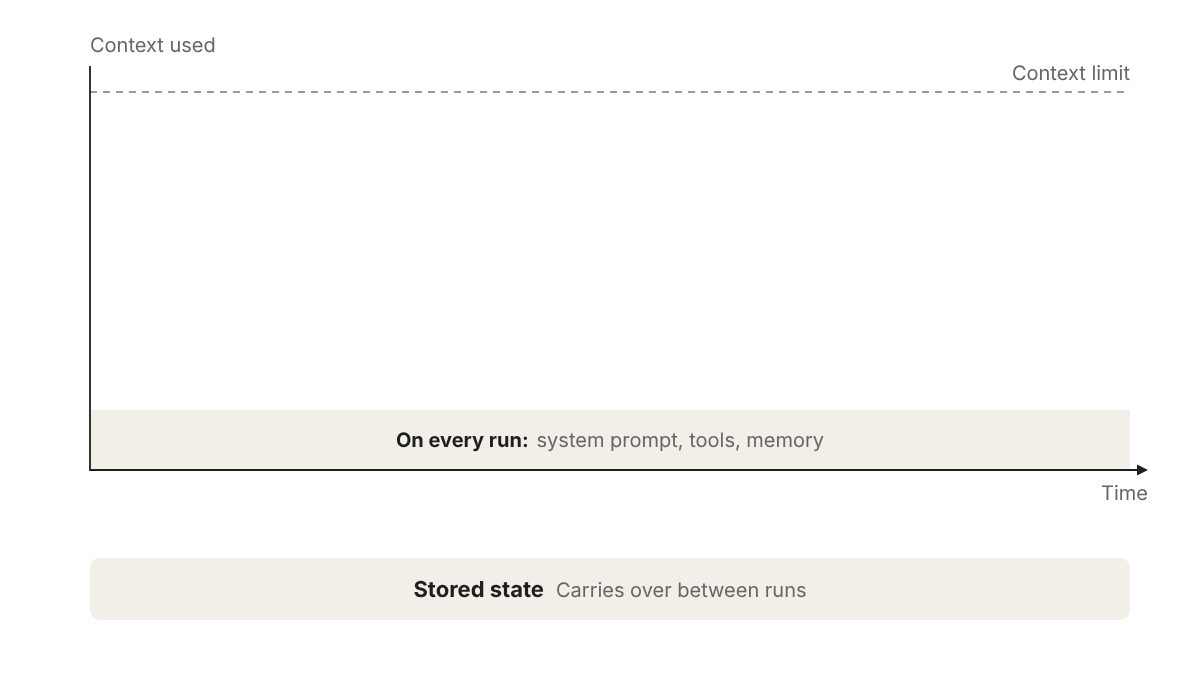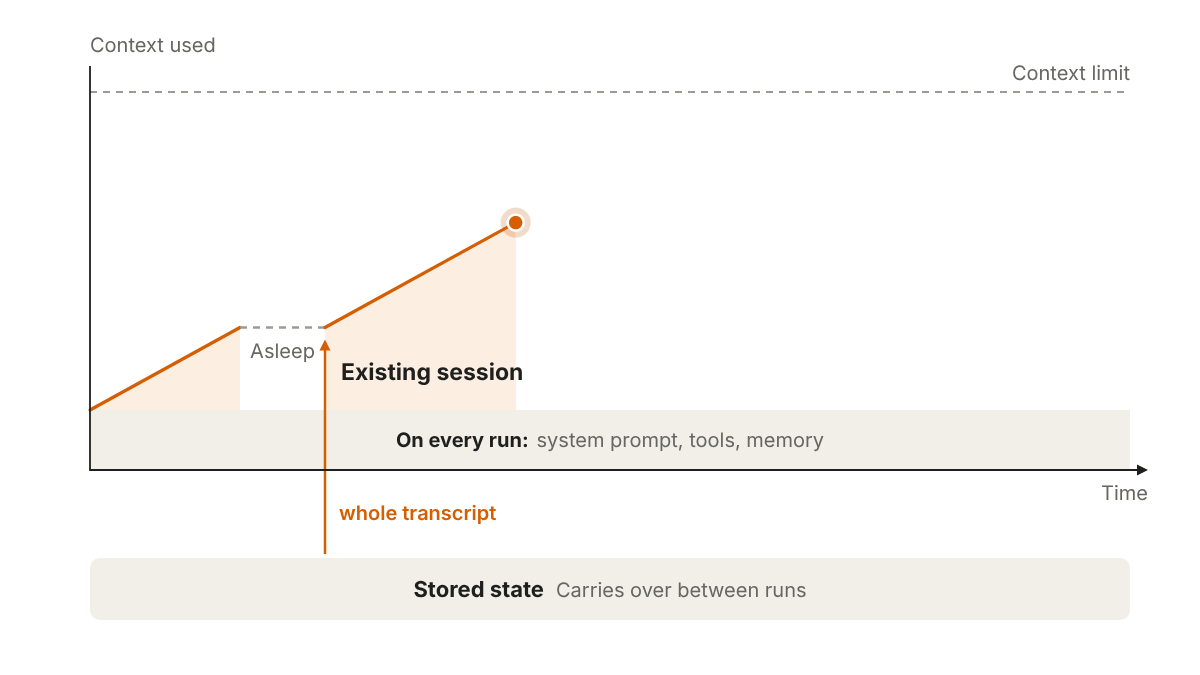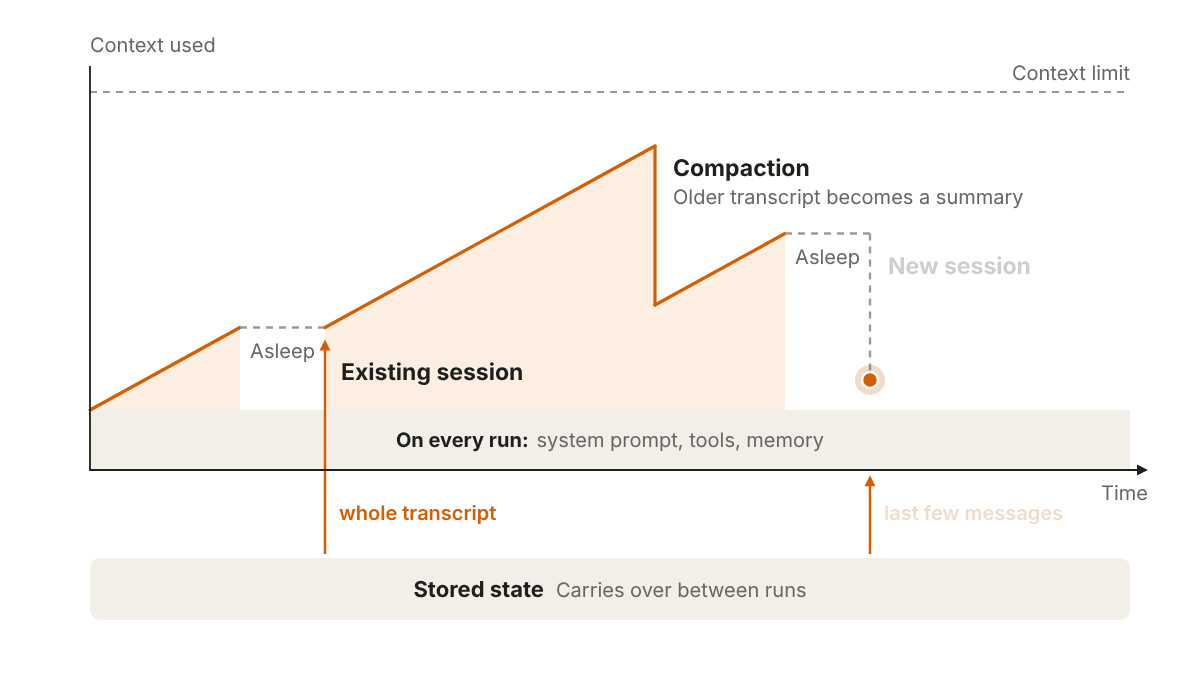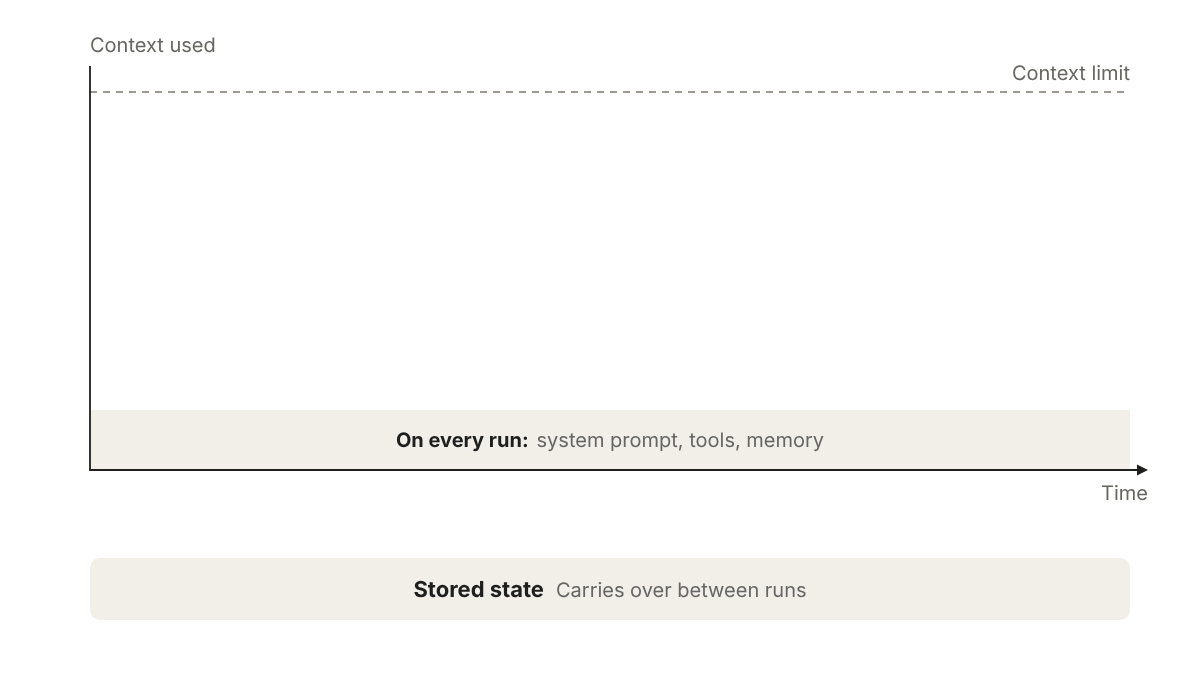
Before doing any work, the agent loads the system prompt, tool definitions, and memory files. This initial context “overhead” is included in every run, so we recommend keeping it lean and using prompt caching to lower costs.
A new session starts only with this context overhead and the events that triggered the run. An existing session, on the other hand, brings back the messages and tool calls from its earlier runs.
If a session becomes too long, you can either compact the older messages or start a new session. Both approaches lose detail, so anything that needs to persist should be saved to memory along the way.
上下文窗口内部
开始干活之前,代理会加载系统提示、工具定义和记忆文件。这部分初始上下文“开销”会出现在每一次运行里,所以我们建议尽量精简,并用 prompt caching 降低成本。
新会话开始时,只有这部分上下文开销,以及触发本次运行的事件。已有会话则会带回此前运行中的消息和工具调用。
如果会话变得太长,你可以压缩较早的消息,或者开启新会话。两种做法都会丢失细节,所以任何需要长期保留的内容,都应该在过程中写入记忆。
Permissions
Permissions are where always-on agents carry the most risk. A run holds the user’s access and, by design, operates unattended. For each tool call, the agent needs to decide whether to proceed on its own, block it, or wait for approval.
The components for permissions are the same ones other agents use:
Credential store: Always-on agents often need sensitive user credentials like passwords or access tokens to be useful. The recommended pattern is a proxy outside the agent’s environment that adds credentials to outgoing requests. The agent sends requests without credentials, and the proxy injects the real credentials before forwarding.
权限
权限是常驻代理风险最大的地方。一次运行持有用户的访问权限,而且按设计是在无人看管下操作的。对每个工具调用,代理都要决定:自己继续、阻止,还是等待批准。
权限用到的组件和其他代理一样:
凭据存储:常驻代理往往需要密码或访问令牌等敏感用户凭据才能发挥作用。推荐模式是在代理环境之外放一个代理层(proxy),由它给外发请求加上凭据。代理发出不带凭据的请求,代理层在转发前注入真实凭据。
Auto mode: An always-on agent should be able to work without constant user input. We’ve already tackled a version of this problem with auto mode in Claude Code. Auto mode uses classifiers to review higher-risk actions and block the ones they identify as dangerous so Claude can find a safer approach. User review, however, is still necessary for the most important decisions.
Deferred tool calls: In Claude Code, a hook can defer a tool call and wait for additional input from the user. The same pattern applies to always-on agents, which may need clarification or approval before taking certain actions. When a call is deferred, the run ends and the session is saved mid-call. The request is shown to the user (e.g., through an interactive card built with MCP Apps), and their answer comes back as an event in the inbox. That event starts a new run, which resumes the saved session with the user’s input. While the deferred call waits for a response, the worker can pick up other events, so the agent isn’t blocked.
自动模式:常驻代理应该能在没有持续用户输入的情况下工作。我们在 Claude Code 的自动模式(auto mode)里已经处理过这类问题。自动模式用分类器审查风险较高的动作,并阻止被判定为危险的动作,让 Claude 寻找更安全的做法。不过,最重要的决策仍然需要用户审核。
延迟工具调用:在 Claude Code 中,hook 可以延迟一次工具调用,等待用户补充输入。同样的模式也适用于常驻代理——它们在采取某些动作前,可能需要澄清或批准。调用被延迟时,运行结束,会话在调用中途被保存。请求会展示给用户(例如通过 MCP Apps 构建的交互卡片),用户的回答作为事件回到收件箱。这个事件会启动新的运行,带着用户输入恢复已保存的会话。延迟调用等待响应期间,worker 可以继续处理其他事件,所以代理不会被阻塞。
Outbox
With most AI agents, the response is streamed to the user as it’s generated, so they can follow along as Claude reasons through the problem, calls tools, and writes its answer.
Always-on agents, on the other hand, do most of their work in the background. The user gets the outcome and a few details, rather than the entire step-by-step breakdown.
A run can end in one of three ways:
The agent sends a message to the outbox,
The agent decides that nothing needs to be sent, or
The agent uses a deferred tool call to request permission or additional input.
发件箱(outbox)
大多数 AI 代理会把响应边生成边流式发给用户,让用户能跟着 Claude 推理、调用工具、写出答案。
常驻代理则把大部分工作放在后台。用户拿到的是结果和少量细节,而不是完整的逐步过程。
一次运行可能以三种方式之一结束:
代理向发件箱发送一条消息,
代理判断不需要发送任何内容,或者
代理使用延迟工具调用,请求权限或补充输入。
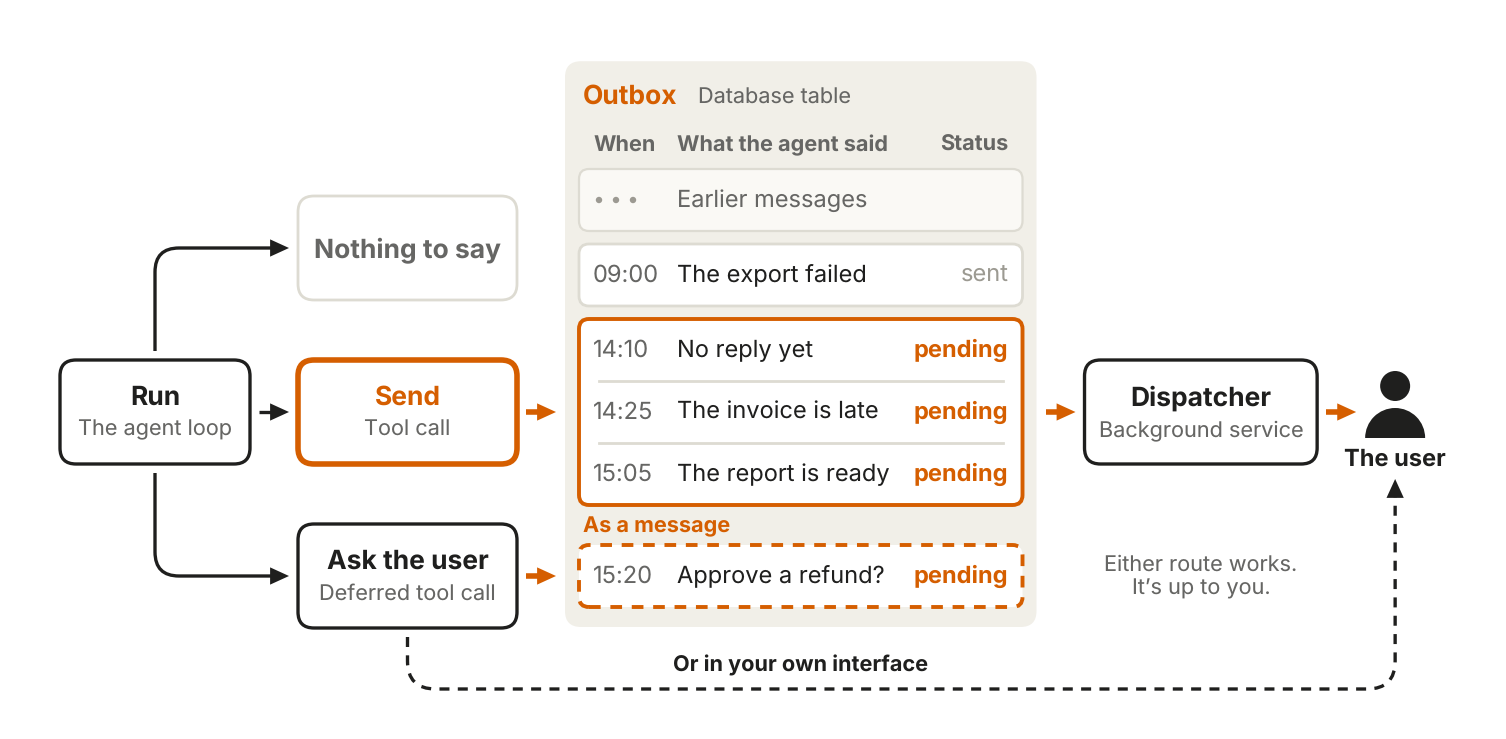
Most always-on agents can get by with a “send” tool that delivers the message directly to the user. You only need a formal outbox when you want to pace your agent’s messages or allow your agent to recover from errors.
The outbox is a separate table of outgoing messages, analogous to the event inbox. There’s also a dispatcher, usually a background service, that’s analogous to the worker. The dispatcher reads the pending messages, decides what to deliver, and sends those to the user. A request from a deferred tool call can either go through the outbox or be shown directly in the interface.
Beyond delivery, it’s important to tune how many messages the agent sends. An agent that sends too many becomes noisy, while an agent that doesn’t send enough misses things that the user needs to know. We recommend building evals to find the right balance. In practice, it’s better for the agent to start quiet and then earn more of the user’s attention over time.
大多数常驻代理用一个“send”工具就能把消息直接送给用户。只有当你需要控制代理发消息的节奏,或者希望代理能从错误中恢复时,才需要正式的 outbox。
outbox 是一张单独的外发消息表,类似事件收件箱。还有一个 dispatcher,通常是后台服务,类似 worker。dispatcher 读取待处理消息,决定要交付哪些,然后把它们发给用户。延迟工具调用产生的请求,可以走 outbox,也可以直接显示在界面里。
除了交付,调好代理发消息的数量也很重要。发得太多,代理会变得吵闹;发得太少,又会漏掉用户需要知道的事。我们建议用 evals 找到合适的平衡。实践中,代理最好先安静,再随着时间赢得用户更多注意力。
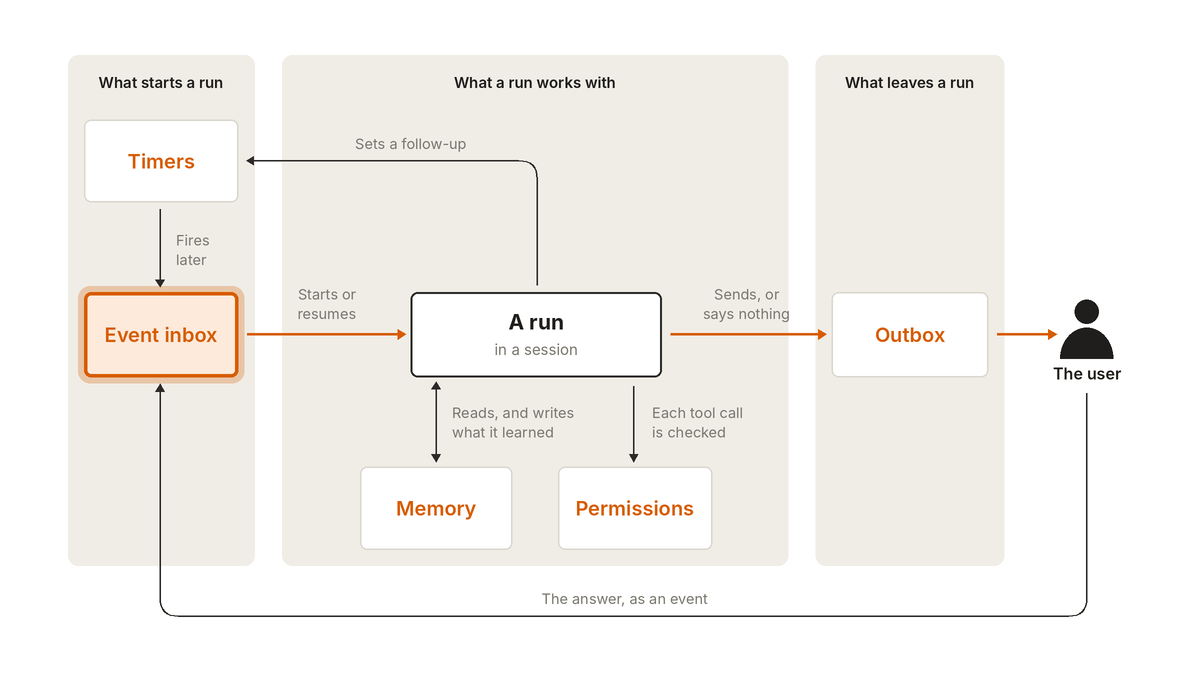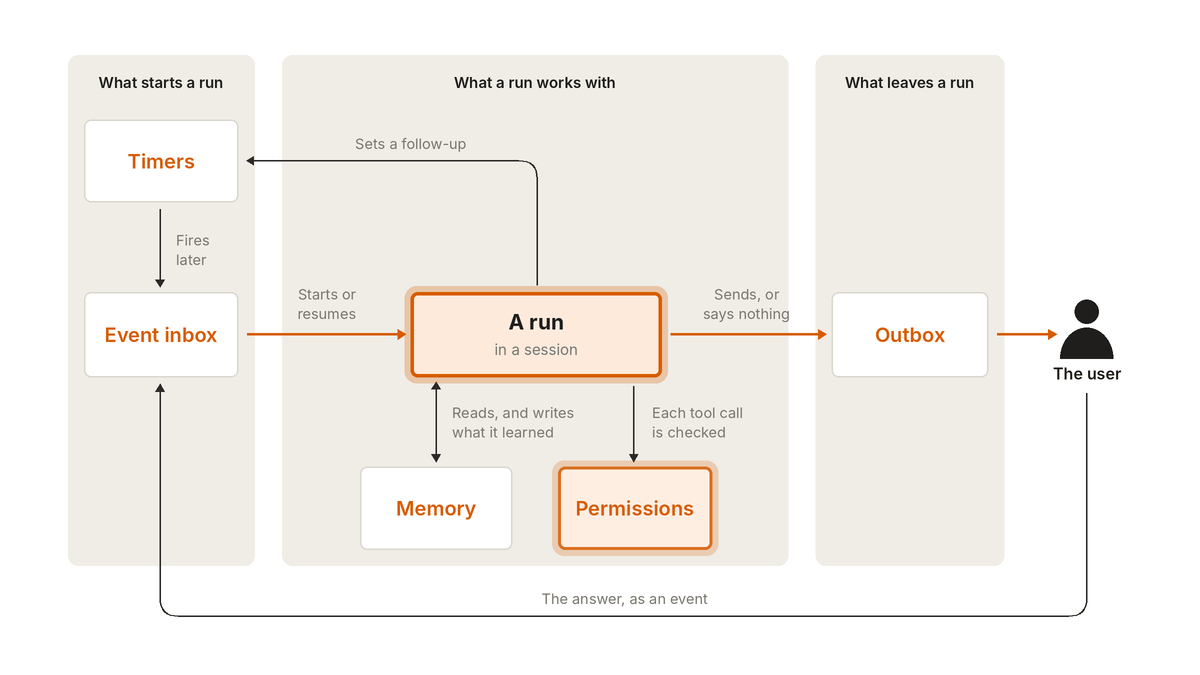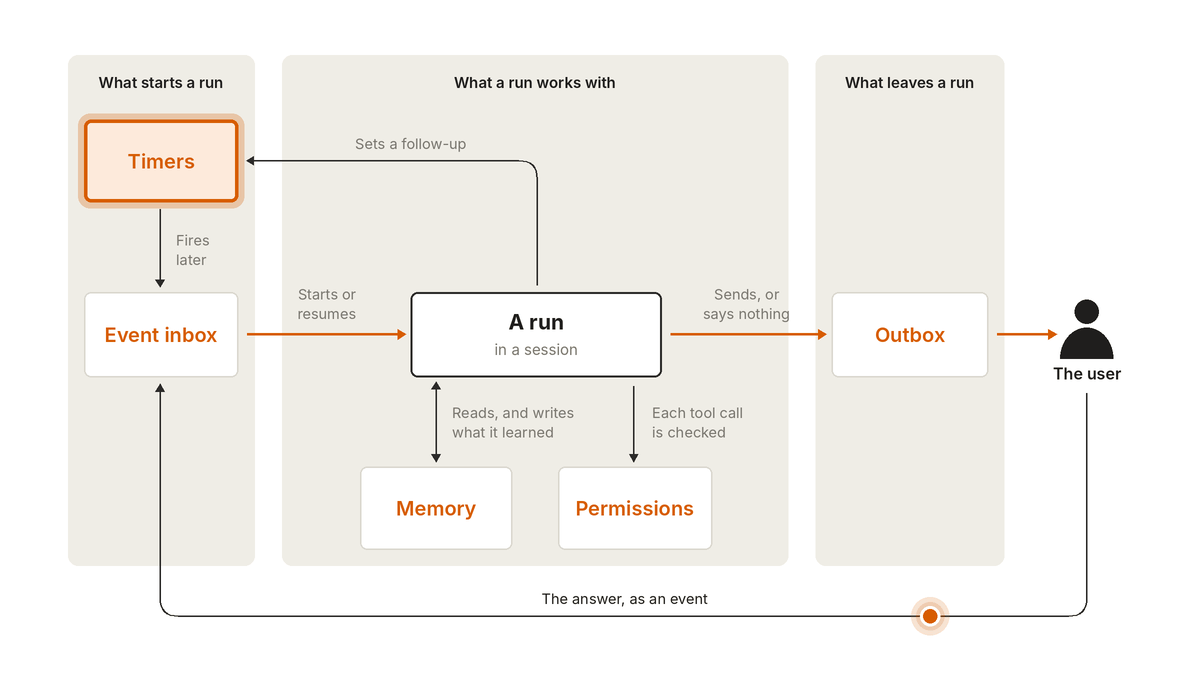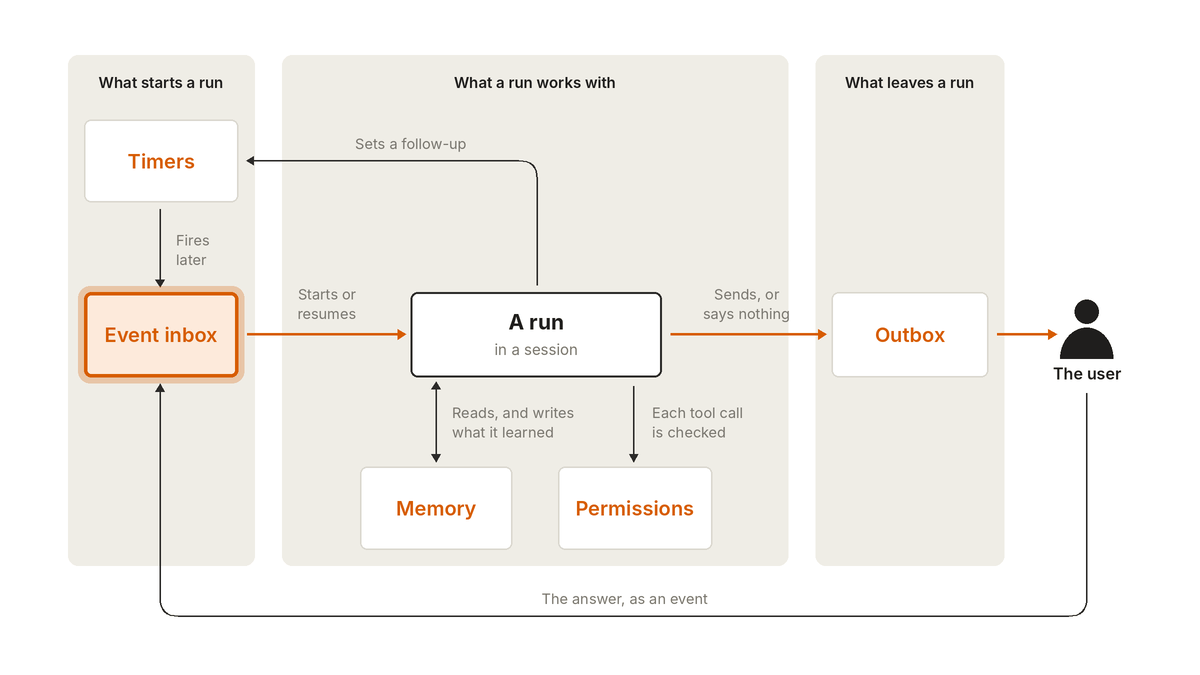
Every run starts with an event from the inbox, whether it’s a user message, a webhook, or a timer. When the worker picks up an event, it kicks off a run and wakes the agent in a new or existing session. The agent reads its memory to get a baseline, works within its permissions to take actions, and then updates its memory with anything it has learned. Once the run is finished, the agent pushes a row to the outbox, and the dispatcher delivers the message to the user.
Together, these form a cycle. A run can set a timer that wakes the agent again later, and when the user replies to a message, their answer comes back as an event in the inbox. Each run is brief, but the cycle keeps going indefinitely, and that’s what makes the agent feel like it’s always on.
每次运行都从收件箱里的一个事件开始,不管是用户消息、webhook 还是定时器。worker 取到事件后,启动一次运行,在新的或已有的会话里唤醒代理。代理读取记忆,获得基线,在权限范围内采取行动,然后把学到的东西写回记忆。运行结束后,代理向发件箱推送一行记录,dispatcher 把消息送达用户。
这些环节合在一起,形成一个循环。一次运行可以设置定时器,稍后再次唤醒代理;用户回复消息时,回答会作为事件回到收件箱。每次运行都很短,但循环会一直转下去——这正是代理让人觉得“始终在线”的原因。
Acknowledgements
Written by William Hu. Special thanks to Rodrigo Olivares and Michael Segner for their contributions.
致谢
本文由 William Hu 撰写。特别感谢 Rodrigo Olivares 和 Michael Segner 的贡献。