Agent 四层栈:先判断坏在 Prompt、Context、Loop 还是 Harness
这篇 X 长文把常被混用的 prompt / context / loop / harness engineering 拆成四层嵌套栈:harness 执行 loop,loop 每一步组装 context,context 里再放 prompt。作者为每层列出工作单元、典型产物与失效症状,并给出一张诊断表——「第 15 轮后质量下降」指向 context 层(剪历史),「重复同一动作」指向 loop 层(补记忆与无进展检测),「重复写库、子进程挂起」指向 harness 层(幂等重试、超时)。核心论断是:验证步骤不跑,改 prompt 无用。文中引用 Karpathy 的 context engineering、Boris Cherny 关于 loop 的说法,以及 LangChain Deep Agents 在 Terminal-Bench 2.0 上仅改 harness 即提分的说法,但未给具体数字。适合做生产级 agent 的工程师当分层排查清单用。

Context engineering, Loop engineering, Harness engineering = upgrades to "Prompt engineering"
They are not interchangeable. They are four layers of the same stack, each with different units of work, failure modes, and tools
- Prompt engineering asks: How do I word this message?
- Context engineering asks: What does the model see on this call?
- Loop engineering asks: What autonomous workflow repeats until a goal is met?
- Harness engineering asks: What code runs the loop, tools, and verification reliably?
Context 工程、Loop 工程、Harness 工程,都是对“Prompt 工程”的升级。
它们不能互换。它们是同一套栈的四个层,每一层的工作单元、失败模式和工具都不同。
- Prompt 工程问的是:这句话我该怎么写?
- Context 工程问的是:这一次调用,模型能看到什么?
- Loop 工程问的是:哪个自主工作流会一直重复,直到目标达成?
- Harness 工程问的是:哪段代码可靠地跑起循环、工具和验证?
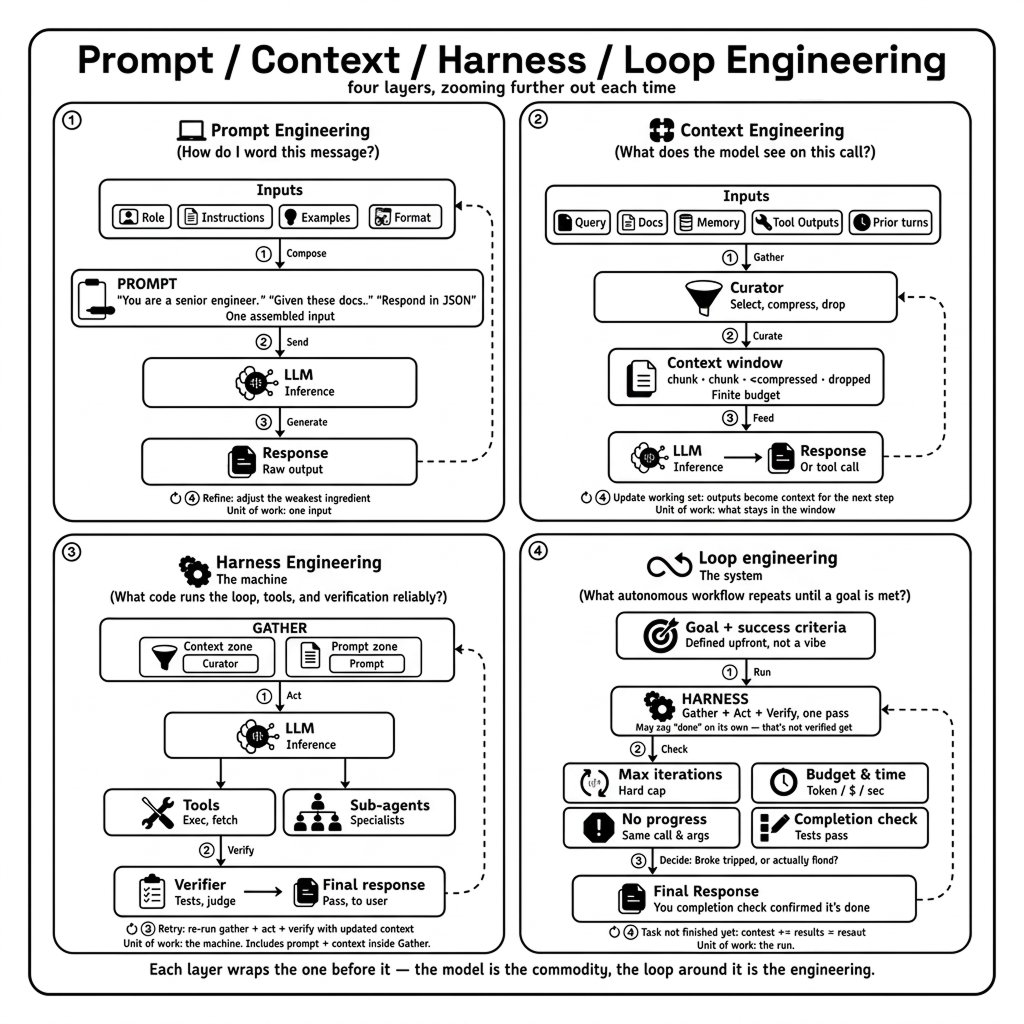
Confusing them is expensive. A team that rewrites prompts when the harness has no verification step will never fix silent failure loops. A team that builds a sophisticated harness with vague goals will burn tokens forever
The same model can also consume radically different token totals across harnesses, but token count alone is not a quality score
把这几层混为一谈,代价很高。一个团队如果在 Harness 缺少验证步骤时反复改 Prompt,就永远修不好静默失败的循环。一个团队如果目标含糊却搭了复杂的 Harness,就会一直烧 token。
同一个模型在不同 Harness 里的 token 总消耗也可能天差地别,但 token 数本身不是质量分数。

This guide maps the full stack - with diagrams, diagnostics, and detailed visuals
| Layer | Unit of work | You design… | Typical artifacts | When it dominates |
|---|---|---|---|---|
| Prompt | One message | Wording, format, CoT, few-shot | System prompt text, user template | Single-turn tasks, prototyping |
| Context | One model call | Full context package | CLAUDE.md, RAG chunks, tool list, history prune rules | Multi-turn agents, RAG, cost control |
| Loop | Entire run | Trigger → goal → verify → memory | /goal, cron, Agent View, triage specs | Autonomous coding, scheduled agents |
| Harness | Runtime execution | Tool sandbox, retries, checkpoints | Claude Code, LangGraph, custom orchestrator | Production reliability, benchmarks |
这篇指南会拆解整座栈——包含图示、诊断方法和详细视觉。
| 层级 | 工作单元 | 你设计的是… | 典型产物 | 何时占主导 |
|---|---|---|---|---|
| Prompt | 一条消息 | 措辞、格式、CoT、few-shot | System prompt 文本、用户模板 | 单轮任务、原型验证 |
| Context | 一次模型调用 | 完整的上下文包 | CLAUDE.md、RAG chunk、工具列表、历史裁剪规则 | 多轮 agent、RAG、成本控制 |
| Loop | 整次运行 | 触发器 → 目标 → 验证 → 记忆 | /goal、cron、Agent View、分诊规格 | 自主编码、定时 agent |
| Harness | 运行时执行 | 工具沙箱、重试、检查点 | Claude Code、LangGraph、自定义 orchestrator | 生产可靠性、基准测试 |
Nesting rule: Harness implements loops → each loop step assembles context → context contains prompts
┌─────────────────────────────────────────────────────────────┐
│  HARNESS ENGINEERING                                        │
│  Runtime: tool exec, sandbox, retries, checkpoints, logs    │
│  ┌───────────────────────────────────────────────────────┐  │
│  │  LOOP ENGINEERING                                     │  │
│  │  Workflow: trigger, goal, actions, verification, memory │  │
│  │  ┌─────────────────────────────────────────────────┐  │  │
│  │  │  CONTEXT ENGINEERING (per iteration)            │  │  │
│  │  │  Assembly: history, RAG, tools, CLAUDE.md, MCP  │  │  │
│  │  │  ┌───────────────────────────────────────────┐  │  │  │
│  │  │  │  PROMPT ENGINEERING (messages inside)     │  │  │  │
│  │  │  │  Wording: role, format, constraints, CoT  │  │  │  │
│  │  │  └───────────────────────────────────────────┘  │  │  │
│  │  └─────────────────────────────────────────────────┘  │  │
│  └───────────────────────────────────────────────────────┘  │
└─────────────────────────────────────────────────────────────┘
         ▲                              ▲
         │                              │
    Boris Cherny:                  Andrej Karpathy:
    "build loops"                  "context engineering"
    (loop + harness)               (context + prompt)
Boris Cherny about self-verification loops:
Boris Cherny: "Two of the most powerful features in Claude Code: /loop and /schedule":
Andrej Karpathy about "context engineering":
嵌套规则:Harness 执行循环 → 循环的每一步组装上下文 → 上下文里包含 Prompt
┌─────────────────────────────────────────────────────────────┐
│  HARNESS ENGINEERING                                        │
│  Runtime: tool exec, sandbox, retries, checkpoints, logs    │
│  ┌───────────────────────────────────────────────────────┐  │
│  │  LOOP ENGINEERING                                     │  │
│  │  Workflow: trigger, goal, actions, verification, memory │  │
│  │  ┌─────────────────────────────────────────────────┐  │  │
│  │  │  CONTEXT ENGINEERING (per iteration)            │  │  │
│  │  │  Assembly: history, RAG, tools, CLAUDE.md, MCP  │  │  │
│  │  │  ┌───────────────────────────────────────────┐  │  │  │
│  │  │  │  PROMPT ENGINEERING (messages inside)     │  │  │  │
│  │  │  │  Wording: role, format, constraints, CoT  │  │  │  │
│  │  │  └───────────────────────────────────────────┘  │  │  │
│  │  └─────────────────────────────────────────────────┘  │  │
│  └───────────────────────────────────────────────────────┘  │
└─────────────────────────────────────────────────────────────┘
         ▲                              ▲
         │                              │
    Boris Cherny:                  Andrej Karpathy:
    "build loops"                  "context engineering"
    (loop + harness)               (context + prompt)
Boris Cherny 谈自我验证循环:
Boris Cherny:“Claude Code 里最强大的两个功能:/loop 和 /schedule”:
Andrej Karpathy 谈“context engineering”:
Think of it like web development:
| Agent stack | Web analogy |
|---|---|
| Prompt | Copy on a single button label |
| Context | Full page layout + data fetched for this view |
| Loop | User journey / multi-step checkout flow |
| Harness | Browser, server, DB, auth, error handling |
可以把它想成 Web 开发:
| Agent 栈 | Web 类比 |
|---|---|
| Prompt | 单个按钮标签上的文案 |
| Context | 整个页面布局 + 这次视图拉取的数据 |
| Loop | 用户旅程 / 多步骤结账流程 |
| Harness | 浏览器、服务器、数据库、鉴权、错误处理 |
Boris Cherny: "I am surprised that people are surprised this is how I prompt Claude."
Definition: Optimizing the text of individual messages, usually the system prompt and current user turn, to elicit better model behavior
Techniques: Chain-of-thought, few-shot examples, role assignment, JSON schema instructions, temperature and sampling controls, system prompt structure
Unit of work: One message pair (system + user) or one turn in a chat
Boris Cherny:“人们居然对我这样给 Claude 写 Prompt 感到惊讶,我才惊讶。”
定义:优化单条消息的文本,通常是 system prompt 和当前用户轮次,以引出更好的模型行为。
技巧:思维链、few-shot 示例、角色设定、JSON schema 指令、temperature 与采样控制、system prompt 结构。
工作单元:一对消息(system + user),或聊天中的一轮。

Example - prompt-level fix:
Before (vague):
Summarize this doc.

After (prompt-engineered):
You are a staff engineer writing release notes for developers.
Output: 3 bullets, each ≤25 words, past tense, no marketing language.
If the doc lacks version numbers, say "Version unclear" — do not invent one.
That improves a single call when the right document is already in context.
When prompt engineering is enough:
- One-shot translation, classification, or formatting
- Early prototyping before you know the workflow shape
- Failures are clearly about misunderstood instructions, not missing files
When it is not enough:
- The model "doesn't know" your codebase → context problem
- The task needs 40 tool calls → loop problem
- Tool calls hang or duplicate writes → harness problem
Context vs prompt engineering:
示例——在 Prompt 层修复:
Before (vague):
Summarize this doc.

After (prompt-engineered):
You are a staff engineer writing release notes for developers.
Output: 3 bullets, each ≤25 words, past tense, no marketing language.
If the doc lacks version numbers, say "Version unclear" — do not invent one.
当正确的文档已经在上下文里时,这能改善单次调用。
Prompt 工程就够用的时候:
- 一次性翻译、分类或格式化
- 还不知道工作流长什么样时的早期原型
- 失败明显是因为指令被误解,而不是缺文件
它不够用的时候:
- 模型“不知道”你的代码库 → 上下文问题
- 任务需要 40 次工具调用 → 循环问题
- 工具调用卡住,或重复写入 → Harness 问题
Context 与 Prompt 工程的分界:

Definition: Designing the full package the model conditions on for each API call
In mid-2026, Karpathy popularized the idea that the real challenge lies in curating the context window:
What lives in the context package
| Component | Context decision | Not a prompt decision |
|---|---|---|
| System prompt | Yes (wording) | Also placement — constraints at top |
| Conversation history | — | Keep, summarize, or drop turns |
| Retrieved docs | — | Which chunks, how many tokens |
| Tool definitions | — | Expose 3 tools or 30? |
| Tool outputs | — | Full stdout vs truncated summary |
| CLAUDE.md | — | Always-loaded project rules |
| SKILL.md | — | Load on trigger only |
| MCP results | — | Live data injected at query time |
The four context levers
- Content selection = does this token earn its place?
- Structure and ordering = constraints first; docs before user message
- Token budget = protect budget for variable content
- Cache placement = stable prefix (system + tools) before cache breakpoint
Example - context-level fix (same user message)
[SYSTEM — always loaded]
Project: [........]. Package manager: pnpm. Tests: pnpm test --filter web.
Never edit apps/mobile without explicit ask.

[RETRIEVED — grep hit, apps/web/lib/pathway-data.ts, lines 40-95]
{relevant_snippet_only}

[TOOLS — this task only]
Read, Edit, Bash(pnpm test:*)

[USER]
Fix the failing pathway progress test.
The user message is boring on purpose. Quality comes from what surrounds it
四个上下文杠杆
- 内容选择 = 这个 token 配不配占位置?
- 结构与顺序 = 约束在前;文档放在用户消息之前
- Token 预算 = 给可变内容留出预算
- 缓存位置 = 稳定前缀(system + tools)放在缓存断点之前
示例——在 Context 层修复(用户消息相同)
[SYSTEM — always loaded]
Project: [........]. Package manager: pnpm. Tests: pnpm test --filter web.
Never edit apps/mobile without explicit ask.

[RETRIEVED — grep hit, apps/web/lib/pathway-data.ts, lines 40-95]
{relevant_snippet_only}

[TOOLS — this task only]
Read, Edit, Bash(pnpm test:*)

[USER]
Fix the failing pathway progress test.
用户消息是故意写得平淡的。质量来自它周围的东西。
Context engineering surfaces in Claude Code:
| Surface | Layer | Loads when |
|---|---|---|
| ~/.claude/CLAUDE.md | Context | Every session |
| ./CLAUDE.md | Context | Project session |
| SKILL.md | Context | Task trigger |
| MCP servers | Context + Harness | Tool call time |
| Context Mode / sandbox MCP | Context + Harness | Isolated file reads |
Full stack breakdown:
Context 工程在 Claude Code 里的入口:
| 入口 | 层级 | 何时加载 |
|---|---|---|
| ~/.claude/CLAUDE.md | Context | 每次会话 |
| ./CLAUDE.md | Context | 项目会话 |
| SKILL.md | Context | 任务触发时 |
| MCP servers | Context + Harness | 工具调用时 |
| Context Mode / sandbox MCP | Context + Harness | 隔离的文件读取 |
全栈拆解:

When context engineering dominates
- RAG pipelines and codebase Q&A
- Sessions beyond ~10 turns (history pollution)
- Tool-selection errors (too many tools exposed)
- Cost/latency (200k context that should be 40k)
Context 工程何时占主导
- RAG 管线和代码库问答
- 超过约 10 轮的会话(历史污染)
- 工具选择错误(暴露了太多工具)
- 成本/延迟(本该 40k 的上下文用了 200k)
Definition: Designing the autonomous workflow that decides when to call the model, what goal must be satisfied, and how to know the run is done without you typing each turn
Addy Osmani popularized loop engineering in June 2026, building on Boris Cherny at Anthropic:
"I don't prompt Claude anymore. I have loops that are running. They're the ones that are prompting Claude and figuring out what to do. My job is to write loops"
Addy Osmani's guide:
The loop still contains prompts = something generates them each iteration. You stop being that something
The five loop components
| Component | Question it answers | Bad design symptom |
|---|---|---|
| Trigger | What starts the run? | You still paste prompts manually |
| Goal | What verifiable state ends it? | Agent "finishes" but tests fail |
| Actions | What tools can it use? | Agent can't reach GitHub/DB |
| Verification | How do we check progress? | Infinite loops or premature stop |
| Memory | What persists across steps? | Re-reads same files, repeats edits |
定义:设计自主工作流,由它决定何时调用模型、必须满足什么目标,以及如何在不靠你手动输入每一轮的情况下知道这次运行已经结束。
Addy Osmani 在 2026 年 6 月推广了 loop engineering,延续 Boris Cherny 在 Anthropic 的实践:
“我不再给 Claude 写 Prompt 了。我有一堆循环在跑。是它们在给 Claude 写 Prompt、决定下一步做什么。我的工作是写循环。”
Addy Osmani 的指南:
循环里仍然包含 Prompt = 每一轮都有东西在生成它们。你不再是那个“东西”。
五个循环组件
| 组件 | 它回答的问题 | 设计糟糕时的症状 |
|---|---|---|
| 触发器 | 什么启动这次运行? | 你还在手动粘贴 Prompt |
| 目标 | 什么可验证状态能结束它? | Agent“完成了”,但测试失败 |
| 动作 | 它能用哪些工具? | Agent 够不到 GitHub/DB |
| 验证 | 我们怎么检查进展? | 无限循环或过早停止 |
| 记忆 | 跨步骤保留什么? | 反复读同一批文件,重复编辑 |
Example - loop spec (not a prompt)
name: morning_p1_triage
trigger: cron "0 8 * * 1-5"
goal: zero open GitHub issues labeled P1 without assignee
actions: [github_mcp.list_issues, github_mcp.comment, github_mcp.assign]
verify: script checks assignee field on all P1 issues
memory: log file of triaged issue IDs this week
max_iterations: 20
human_gate: none  # read/write on issues only
No clever phrasing - workflow architecture
Loop engineering vs prompt engineering:
| Dimension | Prompt | Loop |
|---|---|---|
| Who drives turns | You | System |
| Duration | Seconds | Minutes to hours |
| Output | Text | Verified outcome |
| Leverage | 1× | 10–100× |
| Primary skill | Phrasing | Systems design |
When loops fail (and it's not the prompt)
| Symptom | Loop fix |
|---|---|
| Runs forever | Add max_iterations + no-progress detector |
| Stops after one file | Tighten goal; add test verification |
| Does wrong work confidently | Goal too vague — use verifiable criteria |
| Repeats same edit | Memory / checkpoint missing |
示例——循环规格(不是 Prompt)
name: morning_p1_triage
trigger: cron "0 8 * * 1-5"
goal: zero open GitHub issues labeled P1 without assignee
actions: [github_mcp.list_issues, github_mcp.comment, github_mcp.assign]
verify: script checks assignee field on all P1 issues
memory: log file of triaged issue IDs this week
max_iterations: 20
human_gate: none  # read/write on issues only
没有花哨措辞——这是工作流架构。
Loop 工程 vs Prompt 工程:
| 维度 | Prompt | Loop |
|---|---|---|
| 谁驱动轮次 | 你 | 系统 |
| 时长 | 秒级 | 分钟到小时 |
| 输出 | 文本 | 已验证的结果 |
| 杠杆 | 1× | 10–100× |
| 主要技能 | 措辞 | 系统设计 |
循环失败时(而且不是 Prompt 的锅)
| 症状 | 循环层修复 |
|---|---|
| 永远在跑 | 加 max_iterations + 无进展检测器 |
| 改完一个文件就停 | 收紧目标;加入测试验证 |
| 自信地做错事 | 目标太模糊——改用可验证标准 |
| 重复同一处编辑 | 缺少记忆 / 检查点 |
Definition: Building or configuring the orchestration code that executes loops: parsing model output, calling tools safely, managing retries, assembling context each turn, and enforcing exit conditions
Boris Cherny and Anthropic engineers use harness engineering for the systems that prompt Claude iteratively: observe, plan, act, reflect => over hours
Addy Osmani's guide:
The agent harness is the concrete artifact:
Goal in → context assembly → model call → parse → execute tools
       → capture results → verify → loop or exit → result out
Harness components
| Component | What it does | Loop vs harness |
|---|---|---|
| Task definition | Converts goal to first prompt | Loop designs; harness encodes |
| Context manager | Prunes history, injects memory | Context rules; harness implements |
| Tool executor | Sandboxed bash, MCP, file I/O | Harness |
| Loop controller | Iteration limits, exit signals | Harness |
| Verification | Runs tests, scripts, diff checks | Loop specifies; harness runs |
| Retry / checkpoint | Idempotent retries, resume | Harness |
| Observability | Logs, traces, cost meters | Harness |
定义:构建或配置执行循环的编排代码:解析模型输出、安全调用工具、管理重试、每轮组装上下文,并强制执行退出条件。
Boris Cherny 和 Anthropic 工程师用 harness engineering 指代那些让 Claude 反复迭代的系统:观察、计划、行动、反思 => 持续数小时。
Addy Osmani 的指南:
Agent Harness 是具体的产物:
Goal in → context assembly → model call → parse → execute tools
       → capture results → verify → loop or exit → result out
Harness 组件
| 组件 | 它做什么 | Loop 还是 Harness |
|---|---|---|
| 任务定义 | 把目标转成第一条 Prompt | Loop 设计;Harness 编码 |
| 上下文管理器 | 裁剪历史、注入记忆 | Context 定规则;Harness 实现 |
| 工具执行器 | 沙箱 bash、MCP、文件 I/O | Harness |
| 循环控制器 | 迭代上限、退出信号 | Harness |
| 验证 | 跑测试、脚本、diff 检查 | Loop 指定;Harness 执行 |
| 重试 / 检查点 | 幂等重试、恢复 | Harness |
| 可观测性 | 日志、trace、成本计量 | Harness |
Why harness beats model upgrades on benchmarks
LangChain's Deep Agents team reported gains on Terminal-Bench 2.0 from harness changes alone → same underlying model. The pattern generalizes:
Better harness on the same model > same harness on a better model - for many agentic tasks
Reason: the model only sees what the harness assembles and only gets the retries the harness allows
Products as harnesses
| Product | Harness features |
|---|---|
| Claude Code | Tools, hooks, permission modes, sessions, subagents |
| Cursor / Codex | IDE integration, model routing, agent modes |
| LangGraph | Stateful graphs, checkpoints, human-in-the-loop |
| OpenCode | Open-source coding agent harness |
| Custom | Your retry logic, your verification scripts |
为什么 Harness 在基准上能胜过换模型
LangChain 的 Deep Agents 团队报告,仅靠 Harness 改动就在 Terminal-Bench 2.0 上取得提升 → 底层模型没变。这个模式可以推广:
同一个模型配更好的 Harness > 更好的模型配同样的 Harness——对许多 agentic 任务而言
原因:模型只能看到 Harness 组装给它的东西,也只能得到 Harness 允许的重试。
作为 Harness 的产品
| 产品 | Harness 特性 |
|---|---|
| Claude Code | 工具、hooks、权限模式、会话、subagents |
| Cursor / Codex | IDE 集成、模型路由、agent 模式 |
| LangGraph | 有状态图、检查点、human-in-the-loop |
| OpenCode | 开源编码 agent harness |
| 自定义 | 你的重试逻辑、你的验证脚本 |
Task: "Migrate our auth module to Clerk and make all tests pass."
Prompt layer:
Migrate auth to Clerk. Make tests pass.
Works for a toy repo. Fails on a monorepo in one shot
- Context layer
- Load CLAUDE.md with package manager, test command, auth file map
- Retrieve only apps/web/lib/auth/* via grep - not whole repo
- Expose Edit + Bash(test) tools only Each iteration of the agent sees a sane package
任务:“把我们的 auth 模块迁移到 Clerk,并让所有测试通过。”
Prompt 层:
Migrate auth to Clerk. Make tests pass.
对玩具仓库可以。放到 monorepo 上一次做完就会失败。
- Context 层
- 加载 CLAUDE.md,写入包管理器、测试命令、auth 文件地图
- 只用 grep 检索 apps/web/lib/auth/*——不是整个仓库
- 只暴露 Edit + Bash(test) 工具 Agent 的每一轮都看到一个合理的上下文包。
- Loop layer
trigger: developer runs /goal
goal: pnpm test --filter web exits 0 AND auth routes use Clerk SDK
verify: test command + grep for legacy auth imports
max_iterations: 50
memory: PROGRESS.md updated each checkpoint
Agent runs until verified → not until it says "done"
- Harness layer
- Sandbox bash; block rm -rf
- Hooks run lint after every edit
- Checkpoint git stash every 10 turns
- Retry transient API failures
- Log token usage per step
- Human gate before editing production env files Production shipping requires all four
- Loop 层
trigger: developer runs /goal
goal: pnpm test --filter web exits 0 AND auth routes use Clerk SDK
verify: test command + grep for legacy auth imports
max_iterations: 50
memory: PROGRESS.md updated each checkpoint
Agent 一直跑到验证通过 → 而不是跑到它说“done”。
- Harness 层
- 沙箱运行 bash;禁止 rm -rf
- 每次编辑后由 hooks 跑 lint
- 每 10 轮用 git stash 做检查点
- 重试瞬时 API 失败
- 记录每一步的 token 用量
- 编辑生产环境文件前设置人工闸门
要上生产,四层缺一不可。
Use this when an agent underperforms:
| Symptom | Likely layer | First fix |
|---|---|---|
| Model misunderstands instruction wording | Prompt | Rewrite system prompt; add few-shot |
| Model lacks facts not in prompt text | Context | Add RAG, CLAUDE.md, or file read |
| Model ignores constraints mid-session | Context | Move constraints to top; repeat before user msg |
| Wrong tool selected | Context | Reduce tool surface; improve schemas |
| Quality degrades after turn 15 | Context | Summarize/prune history |
| Never completes task | Loop | Add verifiable goal + test verification |
| Completes but wrongly | Loop | Strengthen verify step |
| Repeats same action | Loop | Add memory + no-progress detector |
| Duplicate emails / double writes | Harness | Idempotent retries, checkpoints |
| Hangs on subprocess | Harness | Timeouts, kill switches |
| Can't debug what happened | Harness | Structured logging, traces |
Fix bottom-up within a layer, outer layers first across layers: if verification never runs, no prompt edit helps
当 agent 表现不佳时,用这张表:
| 症状 | 可能的层 | 第一步修复 |
|---|---|---|
| 模型误解指令措辞 | Prompt | 重写 system prompt;加入 few-shot |
| 模型缺少 Prompt 文本里没有的事实 | Context | 加入 RAG、CLAUDE.md 或文件读取 |
| 模型在会话中途忽略约束 | Context | 把约束移到顶部;在用户消息前重复一遍 |
| 选错工具 | Context | 缩小工具面;改进 schema |
| 第 15 轮后质量下降 | Context | 摘要/裁剪历史 |
| 永远完不成任务 | Loop | 加入可验证目标 + 测试验证 |
| 完成了但做错了 | Loop | 强化验证步骤 |
| 重复同一动作 | Loop | 加入记忆 + 无进展检测器 |
| 重复发邮件 / 双重写入 | Harness | 幂等重试、检查点 |
| 卡在子进程上 | Harness | 超时、kill switch |
| 无法调试发生了什么 | Harness | 结构化日志、trace |
层内自底向上修;跨层先修外层:如果验证根本不跑,改多少 Prompt 都没用。
| Role focus | Primary layers | Secondary |
|---|---|---|
| Content / marketing AI | Prompt, Context | — |
| Support bot with KB | Context, Prompt | Loop (escalation) |
| Internal coding assistant | Context, Loop | Harness (CI integration) |
| Autonomous coding agent | Loop, Harness | Context |
| Platform / agent infra | Harness | Loop, Context |
Prompt engineering is table stakes → like knowing SQL if you build backends
Context engineering is required for any agent that reads your data
Loop engineering is required when you want autonomy measured in hours, not seconds
Harness engineering is required when failure has a cost → money, data, reputation
| 角色重点 | 主要层级 | 次要层级 |
|---|---|---|
| 内容 / 营销 AI | Prompt、Context | — |
| 带知识库的客服 bot | Context、Prompt | Loop(升级) |
| 内部编码助手 | Context、Loop | Harness(CI 集成) |
| 自主编码 agent | Loop、Harness | Context |
| 平台 / agent 基础设施 | Harness | Loop、Context |
Prompt 工程是入场券 → 就像做后端要会 SQL。
Context 工程是所有读取你数据的 agent 的必需品。
Loop 工程是当你要以小时而不是秒来衡量自主性时的必需品。
Harness 工程是当失败有代价时的必需品 → 金钱、数据、声誉。

Prompt, context, loop, and harness engineering are not four names for the same job
They are four layers of one stack:
- Prompt = message wording
- Context = per-call assembly
- Loop = autonomous workflow
- Harness = reliable execution Karpathy named the context crisis. Cherny named the loop shift. Production teams name the harness when benchmarks move without new models
When someone says "we need better prompts" on a long-running agent, ask: "Which layer is actually failing?"
The answer determines whether you edit a paragraph, redesign retrieval, rewrite the goal spec, or fix retry logic
Get the layer right → then optimize inward
Save this so you don't lose it
Follow @beamnxw for more alpha
=> my substack
=> my telegram channel
=> my youtube
=> my github
=> my github works
Prompt、Context、Loop、Harness 工程并不是同一份工作的四个名字。
它们是同一套栈的四层:
- Prompt = 消息措辞
- Context = 每次调用的组装
- Loop = 自主工作流
- Harness = 可靠执行 Karpathy 点出了上下文危机。Cherny 点出了循环转变。生产团队点出 Harness,是因为没有新模型,基准也能动。
当有人在长时运行的 agent 上说“我们需要更好的 Prompt”时,问一句:“到底是哪一层在失败?”
答案决定你是改一段话、重新设计检索、重写目标规格,还是修重试逻辑。
先把层搞对 → 再往里优化。
收藏这篇,别弄丢。
关注 @beamnxw 获取更多 alpha。
=> 我的 substack
=> 我的 telegram 频道
=> 我的 youtube
=> 我的 github
=> 我的 github 作品